> For the complete documentation index, see [llms.txt](https://docs.redivis.com/llms.txt). Markdown versions of documentation pages are available by appending `.md` to page URLs; this page is available as [Markdown](https://docs.redivis.com/reference/workflows/transforms/step-stack.md).

# Step: Stack

## Overview

The **Stack** step will add or remove rows from another table that align with the existing variable structure.

#### Example starting data:

```
Source (t0)             table1 (t1)
/*---------+--------*   /*---------+--------+
 | student | score  |    | student | score  |
 +---------+--------+    +---------+--------+
 | jane    | 83     |    | tom     | 83     |
 | kim     | 35     |    | sherri  | 92     |
 | sam     | 74     |    | pat     | 48     |
 | zay     | 62     |    | jade    | 87     |
 *---------+--------*/   *---------+--------*/
```

#### Example output data:

Union rows from Table B.

```
/*---------+--------*
 | student | score  |
 +---------+--------+
 | jane    | 83     |
 | kim     | 35     |
 | sam     | 74     |
 | pat     | 62     |
 | tom     | 83     |
 | sherri  | 92     |
 | pat     | 48     |
 | jade    | 87     |
 *---------+--------*/
```

## Step structure

<div data-with-frame="true"><figure><img src="https://1672950126-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2F-LVodLwUXgJUGcm5Cvso%2Fuploads%2FGVqvhjEdprg9YNR5uVDA%2FScreenshot%202023-05-04%20at%2011.01.16%20AM.png?alt=media&amp;token=3abcecfb-ca31-4cae-945e-93d949ae774a" alt=""><figcaption></figcaption></figure></div>

## Field descriptions

<table><thead><tr><th width="227">Field</th><th>Description</th></tr></thead><tbody><tr><td><strong>Stacked table</strong></td><td>The table containing the rows you wish to add.</td></tr><tr><td><strong>Stack type</strong></td><td>How the rows will be added.</td></tr><tr><td><strong>Variable alignment</strong></td><td><p>How you define the variable structure between the source and the <code>Stacked table</code>.<br><br><strong>All matching variables</strong>: Will automatically match variables and only include variables with a matching name. The rest will be dropped.</p><p><br><strong>All variables</strong>: Will automatically match variables and keep all variables in the output. Values will be marked <code>null</code> where there is no match for an existing variable<br><br><strong>Manually match variables</strong>: Will require you to align variables between two tables.</p></td></tr><tr><td><strong>Retype variables</strong></td><td>Variables will be retyped in order to be aligned.</td></tr><tr><td><strong>Only keep distinct rows</strong></td><td>If any added rows are an exact duplicate of an existing row, it will be dropped from the output.</td></tr><tr><td><strong>Create variable for table name</strong> (Union only)</td><td>In order to record in the data to indicate where new rows came from, you can opt to create a new variable with table information.</td></tr></tbody></table>

## Stack types

The most common stack type is a Union, which can be useful when combining data which has been broken up into multiple tables with the same structure.

#### Union

Appends all of the stacked table’s rows to the source table.

#### Except

Keep only distinct rows in the source table that match rows in the stacked table.

#### Intersect

Keep only distinct rows that are in the source table and stacked table.

## Examples

### Example 1: Basic union

Let's say we have data broken into two tables with the same structure. We want to add all rows together as they are.

#### Starting data:

```
Source (t0)             table1 (t1)
/*---------+--------*   /*---------+--------+
 | student | score  |    | student | score  |
 +---------+--------+    +---------+--------+
 | jane    | 83     |    | tom     | 83     |
 | kim     | 35     |    | sherri  | 92     |
 | sam     | 74     |    | pat     | 48     |
 | zay     | 62     |    | jade    | 87     |
 *---------+--------*/   *---------+--------*/
```

#### Input fields:

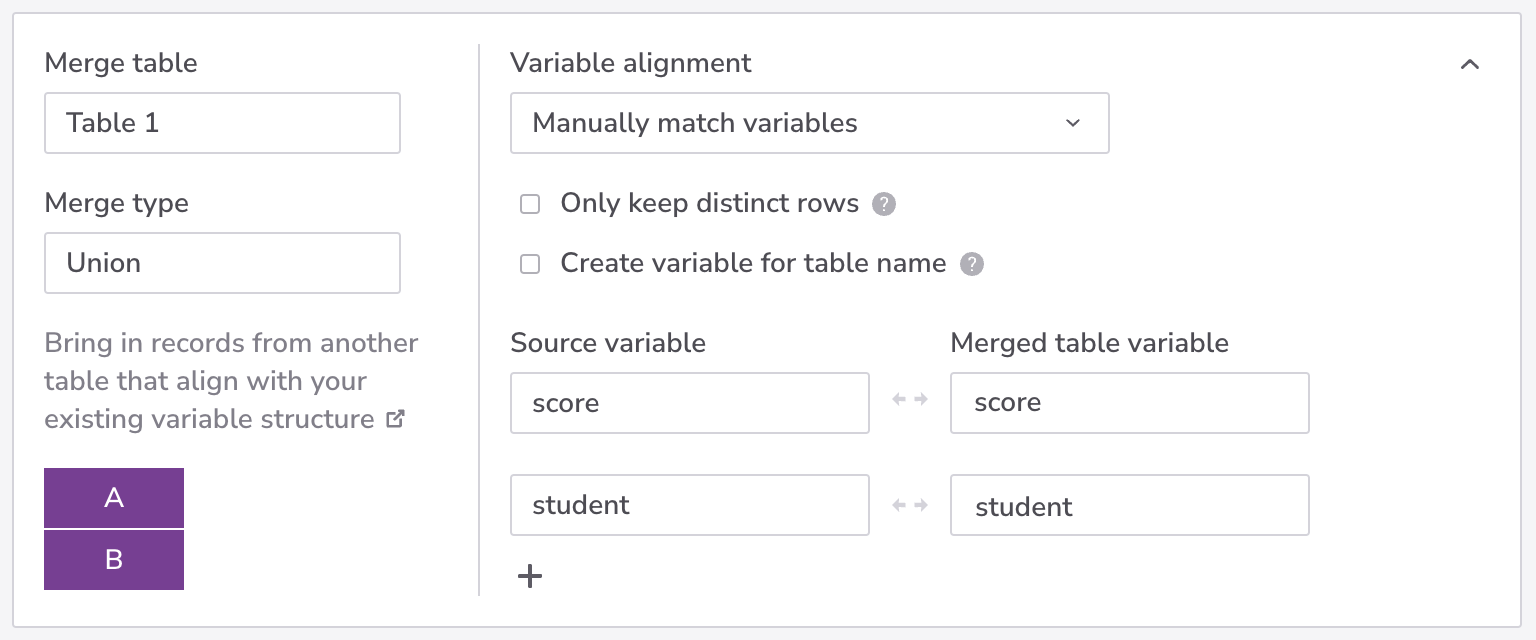
<div data-with-frame="true"><figure><img src="https://1672950126-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2F-LVodLwUXgJUGcm5Cvso%2Fuploads%2FR8if5gckOR3EBVUmS0wK%2FScreenshot%202023-05-04%20at%2011.04.18%20AM.png?alt=media&amp;token=917c5074-39bc-40bd-97fc-74dc6fad382b" alt=""><figcaption></figcaption></figure></div>

* **Stacked table:** The data is in `table1`, so we select that here.
* **Stack type:** We want to add all rows, so we select `Union` here.
* **Variable alignment:** Somehow our variable names shifted between tables, so we can't automatically align tables. We choose `Manually match variables`, then fill in the variable names under `Source variable` and `Stacked table variable`.
  * Where the variable names are different, the output will keep the name of the `Source variable` when it exists.

#### Output data:

```
/*---------+--------*
 | student | score  |
 +---------+--------+
 | jane    | 83     |
 | kim     | 35     |
 | sam     | 74     |
 | pat     | 62     |
 | tom     | 83     |
 | sherri  | 92     |
 | pat     | 48     |
 | jade    | 87     |
 *---------+--------*/   
```

### Example 2: Bulk union and variable misalignment

To continue the previous example, let's say we have a third table of data, and it has additional information that was not present in the first two about `date`. We want to keep this information and also keep track of which rows came from which table.

#### Starting data:

```
Source (t0)             table1 (t1)             table2 (t2)
/*---------+--------*   /*---------+--------*   /*---------+--------+------------*
 | student | score  |    | student | score  |    | student | score  | date       |
 +---------+--------+    +---------+--------+    +---------+--------+------------+
 | jane    | 83     |    | tom     | 83     |    | barb    | 46     | 2020-01-01 |
 | kim     | 35     |    | sherri  | 92     |    | mitch   | 79     | 2020-01-01 |
 | sam     | 74     |    | pat     | 48     |    | oleg    | 68     | 2020-01-01 |
 | zay     | 62     |    | jade    | 87     |    | maria   | 85     | 2020-01-01 |
 *---------+--------*/   *---------+--------*/   *---------+--------+------------*/
```

#### Input fields:

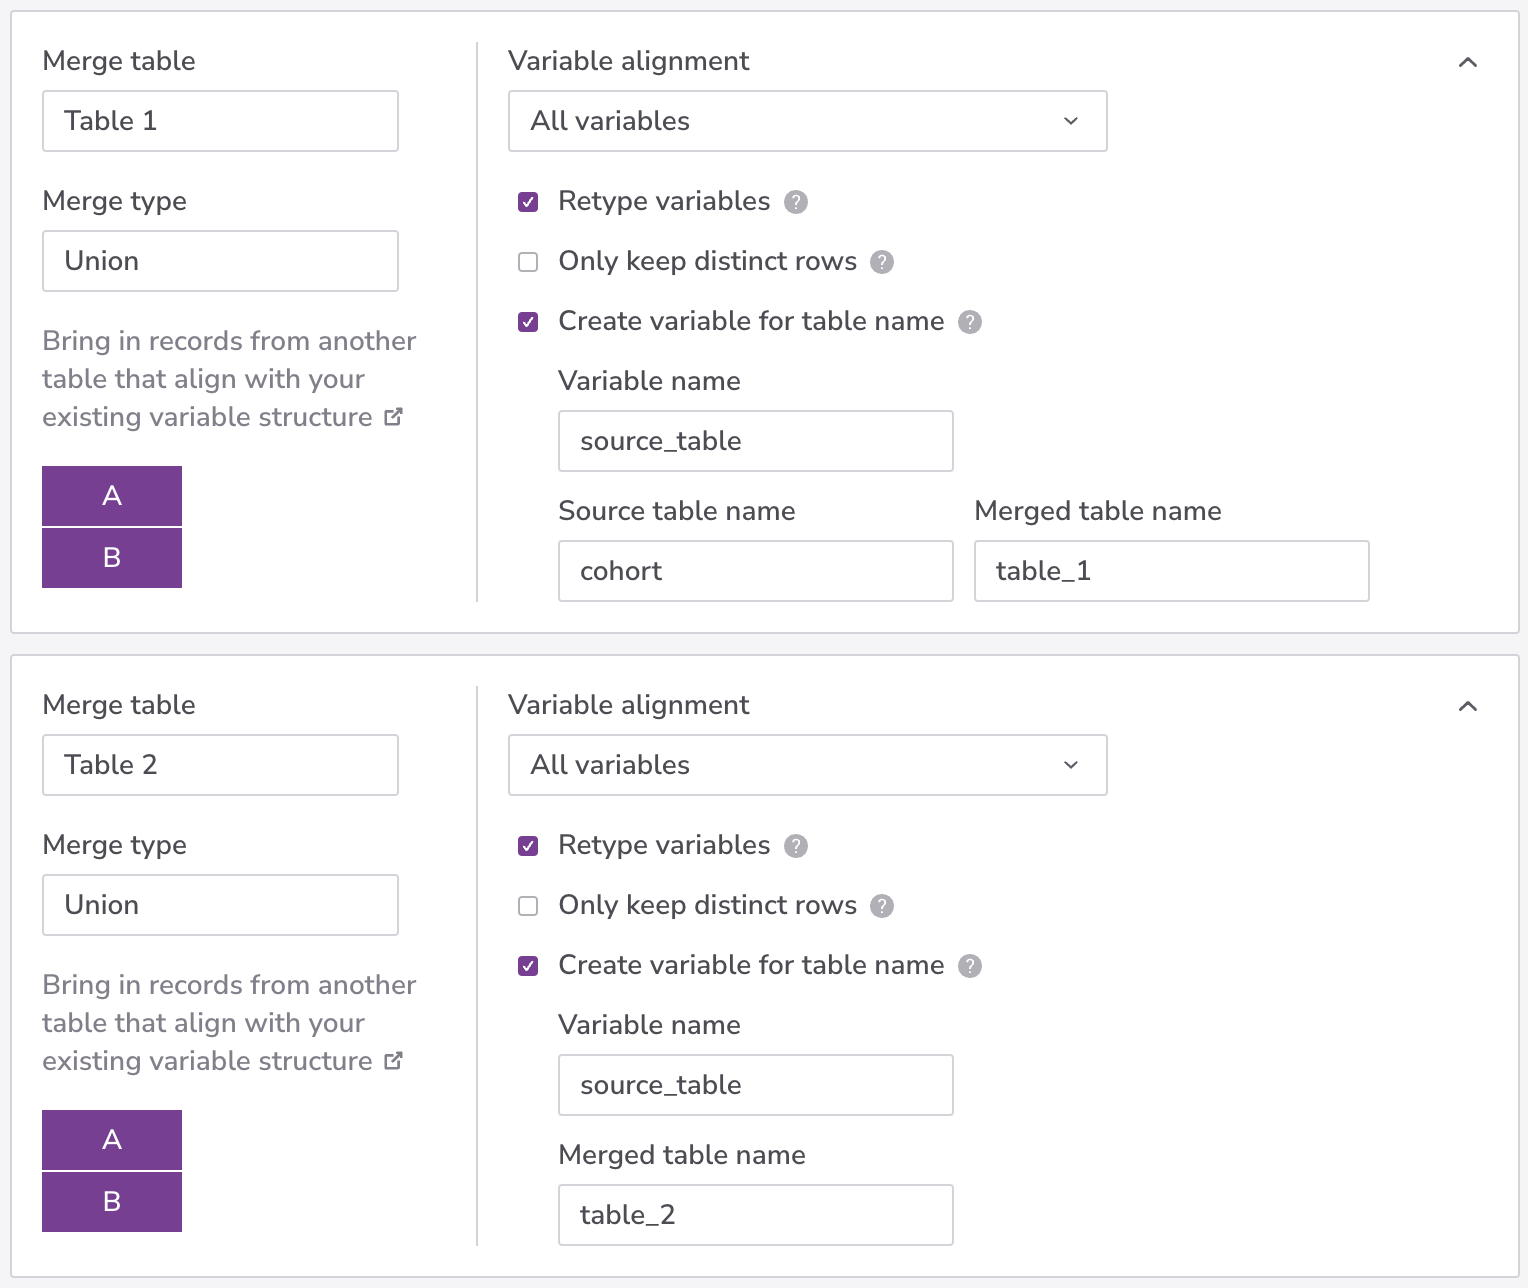
<div data-with-frame="true"><figure><img src="https://1672950126-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2F-LVodLwUXgJUGcm5Cvso%2Fuploads%2FJBDOG5tmwsTCtBCWBSUA%2FScreenshot%202023-05-04%20at%2011.07.26%20AM.png?alt=media&amp;token=bc7bf770-046e-4e38-9ff4-cb74f4e57074" alt=""><figcaption></figcaption></figure></div>

* We create one block for the `t1` union, and a second block for the `t2` union,
* **Variable alignment:** Since we want to keep all variables no matter if they have matches, we select `All variables`.
* **Create variable for table name:** We check this box since we want to keep track of which table each row came from.
  * Note that `Source table name` is automatically populated with the name of this transform's source table.

#### Output data:

```
/*---------+--------+------------+---------------*
 | student | score  | date       | source_table  |
 +---------+--------+------------+---------------+
 | jane    | 83     | null       | cohort        |
 | kim     | 35     | null       | cohort        |
 | sam     | 74     | null       | cohort        |
 | zay     | 62     | null       | cohort        |
 | tom     | 83     | null       | table1        |
 | sherri  | 92     | null       | table1        |
 | pat     | 48     | null       | table1        |
 | jade    | 87     | null       | table1        |
 | barb    | 46     | 2020-01-01 | table2        |
 | mitch   | 79     | 2020-01-01 | table2        |
 | oleg    | 68     | 2020-01-01 | table2        |
 | maria   | 85     | 2020-01-01 | table2        |
 *---------+--------+------------+---------------*/  
```

### Example 3: Except

Let's say we have a table with information about students and their test scores, and we have identified some students that have dropped the course and that we no longer need in the original table. We have gathered those students in `t1`.

#### Starting data:

```
Source (t0)             table1 (t1)
/*--------+-------*      /*------+-------*
 | name   | score |       | name | score |
 +--------+-------+       +------+-------+
 | jane   | 83    |       | kim  | 35    |
 | kim    | 35    |       | pat  | 48    |
 | sam    | 74    |       *------+-------*/
 | pat    | 62    | 
 | tom    | 83    |
 | sherri | 92    |
 *--------+-------*/       
```

#### Input fields:

<div data-with-frame="true"><figure><img src="https://1672950126-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2F-LVodLwUXgJUGcm5Cvso%2Fuploads%2FSQ1Lnwxeww7SakDkFRKT%2FScreenshot%202023-05-04%20at%2011.08.17%20AM.png?alt=media&amp;token=4413f7f1-11e5-45d5-a304-697f62a44ced" alt=""><figcaption></figcaption></figure></div>

#### Output data:

<pre><code>/*--------+-------*
 | name   | score |
 +--------+-------+
 | jane   | 83    |
 | sam    | 74    |
 | tom    | 83    |
 | sherri | 92    |
<strong> *--------+-------*/       
</strong></code></pre>

The rows that were in both tables are now removed.

### Example 4: Intersect

Let's say we have two tables full of students, one from who took our fall semester class, and one from the spring semester class. We want to only keep student rows for people who took both classes, so those who are present in both tables.

```
Source (t0)             table1 (t1)
/*--------+-------*      /*------+-------*
 | name   | id    |       | name | id    |
 +--------+-------+       +------+-------+
 | jane   | 101   |       | kim  | 104   |
 | kim    | 104   |       | pat  | 108   |
 | sam    | 105   |       | mae  | 109   |       
 | pat    | 108   |       | zay  | 110   | 
 | tom    | 112   |       | jade | 111   |
 | sherri | 117   |       | tom  | 112   |
 *--------+-------*/      *------+-------*/      
```

#### Input fields

<div data-with-frame="true"><figure><img src="https://1672950126-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2F-LVodLwUXgJUGcm5Cvso%2Fuploads%2FApfQe709YLx2PBgEWnzN%2FScreenshot%202023-04-26%20at%202.26.59%20AM.png?alt=media&amp;token=9593ab02-d453-4fa1-8e30-78ed758f40b6" alt=""><figcaption></figcaption></figure></div>

#### Output data:

```
/*------+-------*
 | name | id    |
 +------+-------+
 | kim  | 104   |
 | pat  | 108   |
 | tom  | 112   |
 *------+-------*/     
```

Only rows that were in both tables now remain.


---

# Agent Instructions
This documentation is published with GitBook. GitBook is the documentation platform designed so that both humans and AI agents can read, navigate, and reason over technical content effectively. Learn more at gitbook.com.

## Querying This Documentation
If you need additional information that is not directly available in this page, you can query the documentation by asking a question.

Perform an HTTP GET request on the following URL with the `ask` and `goal` query parameters:

```
GET https://docs.redivis.com/reference/workflows/transforms/step-stack.md?ask=<question>&goal=<user_goal>
```

`ask` is the immediate question: it should be specific, self-contained, and written in natural language.
`goal` is what the user is ultimately trying to achieve, the reason they need the answer. Sharing it helps GitBook give you a better, more relevant answer. A goal is most helpful when it describes the outcome the user wants rather than restating the question. For example, with `ask=how do I create an API token`, a goal like `automate deployments from our CI pipeline` lets GitBook tailor the answer to that use case.

The response will contain a direct answer to the question and relevant excerpts and sources from the documentation.

Use this mechanism when the answer is not explicitly present in the current page, you need clarification or additional context, or you want to retrieve related documentation sections.